Zhiyuan Li 李Lǐ志Zhì圆Yuán

Postdoctoral Researcher @ Aalto Robot Learning Lab, Aalto University Espoo, Finland

I am a postdoctoral researcher at the Aalto Robot Learning Lab, Aalto University, working with Prof. Joni Pajarinen. I study how learning agents coordinate — with each other and with the physical world: multi-agent reinforcement learning, object-centric representations of video, and transfer from human video to robot embodiments.

I received my Ph.D. in Computer Science and Technology from the University of Electronic Science and Technology of China (2024) and my B.S. from North China Electric Power University (2019). During my Ph.D. I spent a year at Aalto as a CSC-funded visiting researcher.

Avatar of Zhiyuan Li

Research Interests

Multi-Agent Systems Reinforcement Learning Robotics Foundation Models

Education

University of Electronic Science and Technology of China
Ph.D. in Computer Science and TechnologySep 2019 – Jul 2024
North China Electric Power University
B.S. in Computer Science and TechnologySep 2015 – Jul 2019

Experience

Aalto Robot Learning Lab, Aalto University
Postdoctoral Researcher · Host: Prof. Joni PajarinenAug 2024 – Present
Aalto University
Visiting Ph.D. Researcher (CSC-funded)Nov 2022 – Dec 2023

Honors & Awards

  • China Scholarship Council (CSC) Scholarship2022
  • Academic Scholarship, UESTC2019–2022
  • Honorable Mention, Mathematical Contest in Modeling (MCM)2017

Service

  • Area Chair: ICLR 2027
  • Reviewer: NeurIPS, ICML, ICLR, AAAI, ECCV, AAMAS

Teaching

  • Main teaching assistant, ELEC-E8125 Reinforcement Learning, Aalto University — 243 students; coordinated a 12-person TA team.
  • Guest lecturer, ELEC-E8125 Reinforcement Learning, Aalto University, 2026 — delivered the advanced part of Lecture 6 (Actor–Critic).

News

2026
2025
2024

Selected Publications

Google Scholar

Rethinking Temporal Consistency in Video Object-Centric Learning: From Prediction to Correspondence

Zhiyuan Li, Rongzhen Zhao, Wenyan Yang, Wenshuai Zhao, Pekka Marttinen, Joni Pajarinen

ICML 2026 Conference

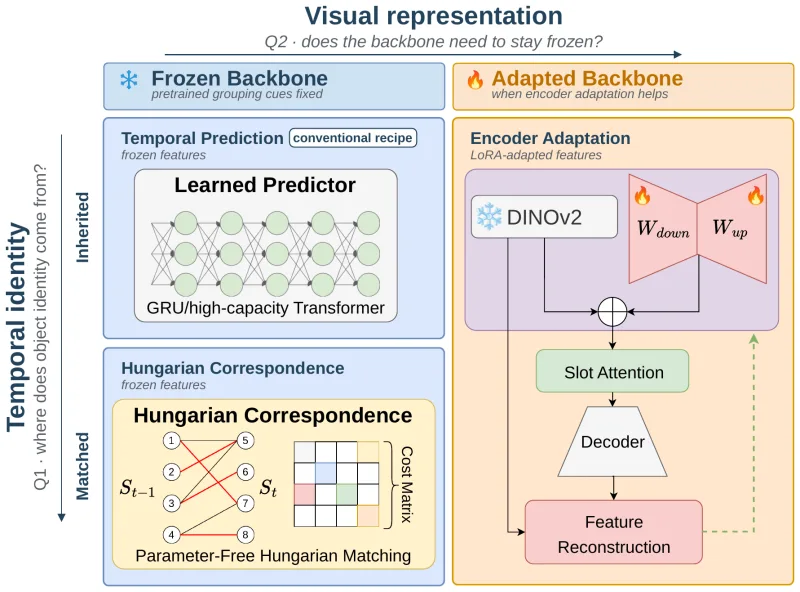
Learned temporal predictors in video object-centric models mostly just keep slot indices stable, so seeding slots from saliency peaks in frozen DINOv2 features and Hungarian-matching them across frames does the same job with no learned temporal parameters.